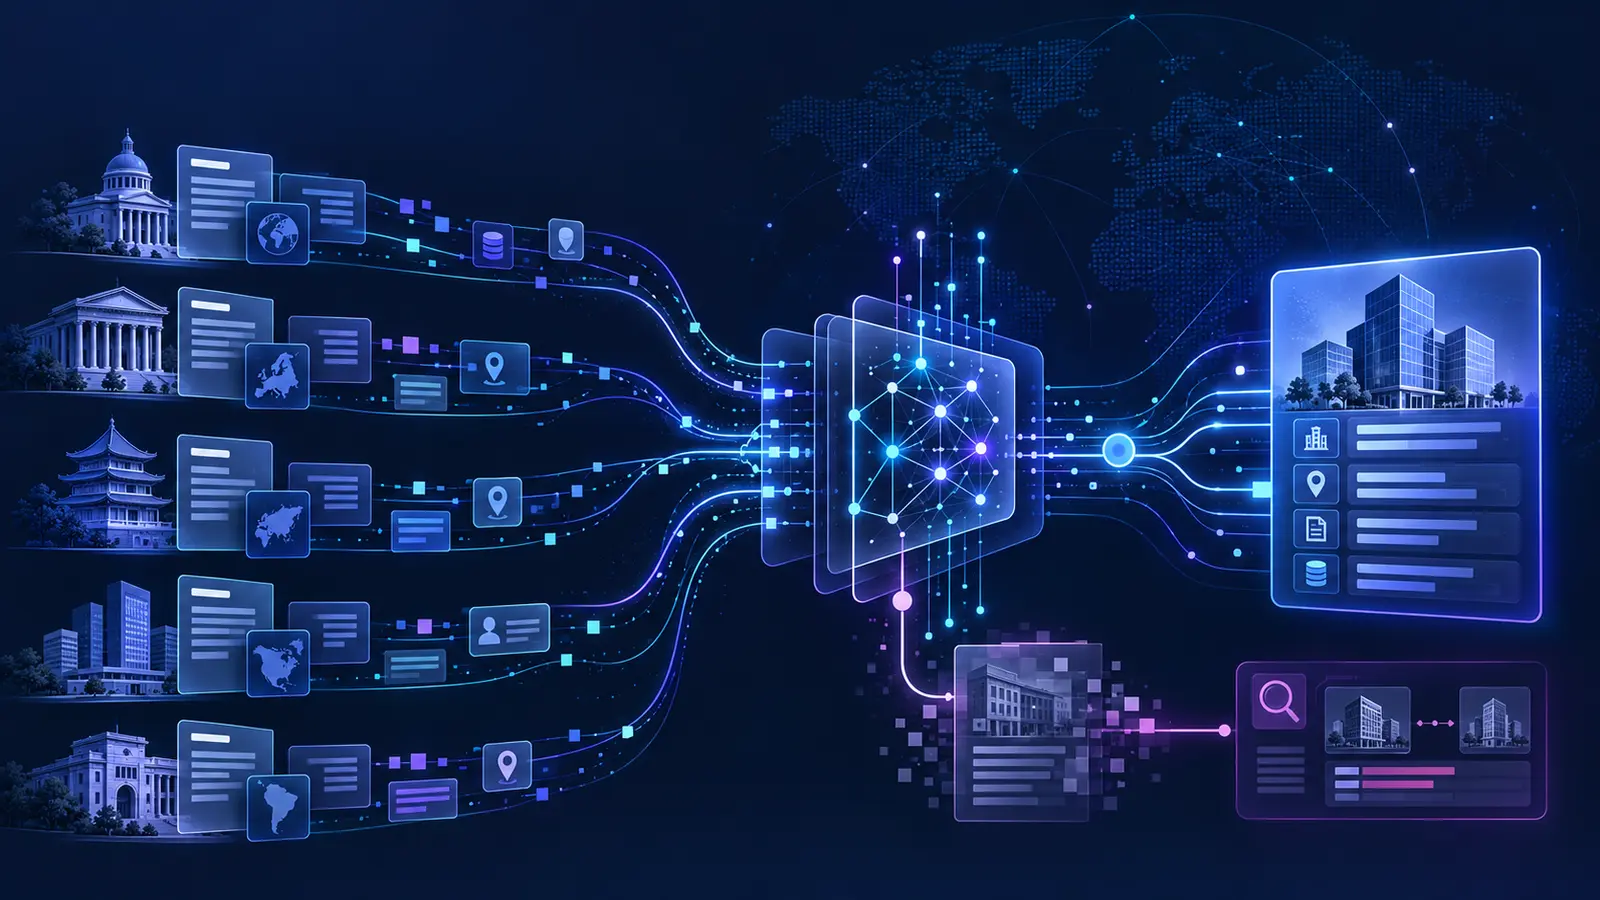
Entity resolution software identifies records that refer to the same real-world entity and links them to a stable identity. For company data, that means deciding whether a supplier record, registry filing, CRM account, payment beneficiary and ownership node represent one legal company, several related companies or genuinely different businesses.
The output is often described as a golden record, but that phrase can hide the most important work. A reliable result is not simply a merged row. It preserves the source records, the rules and evidence used to connect them, the relationships between related entities and the uncertainty that remains.
Company entity resolution typically has four jobs:
- standardise names, addresses, identifiers and jurisdiction values without destroying the original source data;
- match records that refer to the same registered company;
- separate branches, subsidiaries, parents, trading names and similarly named businesses;
- maintain the decision as filings, names, addresses and corporate relationships change.
This is different from simple deduplication. Deduplication finds repeated rows inside a dataset. Entity resolution can connect incomplete and inconsistent records across many systems, then distinguish identity from corporate relationship. Two records may describe different legal entities in the same group; merging them would remove information rather than improve it.
Entity resolution is the controlled process of turning source records into identity decisions: same entity, different entity, related entity or unresolved. Software should show why each decision was made and retain enough evidence for it to be reproduced.
Resolution is the foundation for KYB verification, supplier onboarding, sanctions screening, ownership analysis, CRM enrichment and portfolio monitoring. If the subject is wrong, every downstream risk result is attached to the wrong company.
Why company entity resolution is difficult
People often assume that companies are easy to match because they have legal names and registration numbers. In practice, enterprise systems rarely receive a complete, current identifier. A purchase order may contain a trading name, a bank file may abbreviate the beneficiary, a CRM may store the global parent and an official filing may use the local legal name and script.
Names are evidence, not identity
Legal suffixes, punctuation, transliteration and word order vary. The same company may appear with and without “Limited”, in a local alphabet, under a former name or as a brand. At the same time, unrelated companies can share nearly identical names. Removing every suffix and accepting a high string similarity can create confident false matches.
Identifiers are powerful but scoped
A company number is normally meaningful within a particular registry and jurisdiction. The digits alone may not be globally unique. VAT numbers, tax identifiers, LEIs, exchange tickers and internal vendor IDs each describe a different identifier system, population and purpose. Software must store the identifier type and issuing authority, not only the value.
Addresses change and are reused
Registered offices, operating sites, mailing addresses and virtual-office locations are not interchangeable. Several legitimate companies can share an address, while one business can have many locations. Address agreement supports a match but should rarely be treated as conclusive by itself.
Corporate relationships are not duplicates
A parent and subsidiary can share a website, brand, officers and address. A branch may use the parent’s name but have a separate local identifier. A merger or conversion can create a successor relationship rather than a duplicate. The resolution model needs relationship types so it can connect these records without collapsing them.
Source data changes at different speeds
Internal master data, registry filings, commercial datasets and company-supplied documents can describe different effective dates. A mismatch may reflect latency rather than error. Keep source and effective dates so the system can distinguish historical truth from a current conflict.
Five ways a plausible company match can be wrong
Risk frameworkA record can look similar for several reasons. The software must explain which identity signal is decisive and which similarities are merely supporting evidence.
A reliable entity resolution workflow for company data
A production workflow should separate data preparation, candidate selection and final decisioning. This makes the process faster without allowing a broad search rule to become an automatic match rule.
1. Preserve and profile the source record
Store the value exactly as received, its system, retrieval time and business context. Profile completeness before normalisation. A blank company number and a number that failed validation are different states and should not be converted into the same null value.
2. Normalise by country and field type
Standardise case, whitespace, common legal forms, address components and identifier formatting using jurisdiction-aware rules. Keep both the raw and normalised versions. Transliteration can create a searchable comparison value, but it should not replace the official-script name.
3. Generate a narrow candidate set
Candidate generation, sometimes called blocking, finds plausible entities without comparing every incoming record with the whole database. Strong keys can include jurisdiction plus registration number. Weaker records may use country, postcode, name tokens, domain or address elements. Candidate rules should favour recall: the correct entity needs to enter the candidate set before detailed scoring can help.
4. Compare identity signals
Evaluate the candidate on field-specific logic. Exact identifier agreement is different from name similarity. A domain may support the match, while a conflicting jurisdiction can veto it. Compare current and former values when history is relevant.
5. Apply deterministic rules and probabilistic evidence
High-confidence deterministic matches can be accepted when identifiers are valid and scoped correctly. Probabilistic or machine-learning models can combine partial evidence for harder records. The model should not erase hard contradictions or invent certainty where required fields are absent.
6. Separate identity from relationship
Once the legal company is resolved, attach parent, subsidiary, branch, successor, shareholder and trading-name relationships as separate edges. This supports a useful beneficial ownership investigation without merging the entities in the ownership chain.
7. Route ambiguity to review
Records near a decision boundary, candidates with material conflicts and high-risk use cases should enter a review queue. Give the reviewer the top candidates, agreement and conflict reasons, source evidence and a way to record the final disposition.
8. Re-resolve after meaningful change
A match is not permanent. Name changes, relocations, mergers, dissolutions and new identifiers can change the best answer. Re-run affected records when the linked company or source record changes, then preserve the previous match decision for audit.
From raw record to governed company identity
Operating modelCandidate generation finds possibilities; decision rules determine identity. Keeping those stages separate prevents a loose search from becoming an unexplained match.
Which signals should entity resolution software use?
No field has the same reliability in every country and source. A good platform treats signals according to their scope, provenance and contradiction risk rather than giving every populated field a generic similarity weight.
- Official identifier
- Registration number plus jurisdiction or issuing registry. Usually the strongest company identity key when valid and current.
- Legal name
- Current and former names, local-script forms, legal suffixes and trading names. Strong evidence when interpreted in context, but rarely globally unique.
- Registered address
- Useful for disambiguation and history. Shared offices and address changes reduce its independent strength.
- Tax and market identifiers
- VAT, EIN, tax, LEI and ticker values can be powerful when the identifier type, country and validity are known.
- Website and contact data
- Domain, email and telephone values help connect operating records but can be shared across a group or change without a legal event.
- People and relationships
- Directors, shareholders and parents add context. They are better used as corroborating or relationship evidence than as automatic identity keys.
Source provenance matters as much as value agreement. The same identifier copied through three aggregators is one underlying claim, not three independent confirmations. Preserve the original registry or filing reference where available and expose the lineage to reviewers. CompanyDelta’s sources and evidence model describes how source name, date and retrieval context should travel with a company fact.
Use identity signals for the job they can support
Evidence matrixThe same value can support different conclusions. A shared domain may indicate a group relationship without proving that two legal-company records are duplicates.
Design match decisions for explainability
A confidence score alone is not an explanation. Reviewers need to know which values agreed, which conflicted, which sources were used and whether a decisive field was absent. Two records can receive similar scores for very different reasons.
Use explicit outcomes:
- confirmed match when scoped identifiers or a strong combination of evidence support the same legal entity;
- confirmed non-match when evidence shows different legal entities;
- related entity when records describe distinct companies connected by a parent, branch, ownership or successor relationship;
- possible match when evidence is promising but incomplete;
- unresolved when candidates conflict or required evidence is unavailable.
Every automated match should return reason codes such as “registration number and jurisdiction agree”, “former legal name agrees”, “country conflicts” or “shared domain, different company numbers”. Store the model or ruleset version with the decision. If rules change, teams can identify which earlier matches need reprocessing.
Do not train on reviewer decisions without checking consistency. If analysts use different standards, a model can learn inconsistent policy rather than real identity. Create adjudicated examples for difficult cases and review false positives and false negatives separately.
Agreement strength and conflict severity drive the outcome
Decision matrixStrong agreement should not silently override a decisive contradiction. A matching name and domain cannot neutralise two different official company identifiers.
How to evaluate entity resolution software
Product demonstrations often use clean records with obvious answers. A meaningful evaluation uses your difficult data and measures the consequences of being wrong.
Start with the legal-entity use case
Define the target entity and downstream decision. Customer identity resolution, household matching, healthcare patient matching and company resolution are different problems. A platform that is excellent at joining consumer profiles may not understand company numbers, registry jurisdictions or parent-subsidiary boundaries.
Test representative jurisdictions and scripts
Include countries with different identifier formats, legal suffixes, address conventions, transliteration needs and registry availability. Use active, dissolved, renamed and newly registered companies. Include branches and companies in the same corporate group.
Build a labelled truth set
Create examples for confirmed matches, confirmed non-matches, related companies and genuinely unresolved records. Have difficult cases independently reviewed, then adjudicate disagreements. A truth set that contains only easy duplicates will exaggerate performance.
Measure the right errors
Precision asks how many accepted matches were correct. Recall asks how many true matches were found. Both matter, but the acceptable balance depends on the workflow. A false positive in sanctions screening or payment onboarding can be more damaging than an unresolved record routed for review. Report results by country, source and completeness band rather than only one global average.
Inspect operational behaviour
Measure review volume, decision latency, stability after data updates and the proportion of outcomes with usable reason codes. Check whether analysts can correct a match without corrupting future learning. Test batch files, real-time APIs and failure handling at the scale you expect to operate.
Review governance and portability
Ask where the source data, match evidence and reviewer decisions are stored; how rules and models are versioned; and whether resolved identifiers can be exported. A company identity layer becomes critical infrastructure. Teams need to understand how they would reproduce or migrate decisions.
CompanyDelta’s company data API and coverage view can supply identifier, registry and relationship context for a resolution workflow. The company data quality checklist provides a broader control framework for source freshness, duplicate handling and approved updates.
A useful proof of concept tests more than match rate
Evaluation scorecardThe best proof of concept connects technical accuracy to the review queue, downstream decisions and the durability of resolved IDs.
A focused implementation plan
Inventory identity fields and decisions
Map every source, identifier type, jurisdiction field, current matching rule and downstream consumer. Identify where a wrong match causes financial, compliance or customer impact.
Create stable company IDs
Assign an internal resolved-entity ID that does not change when a name or address changes. Link source records to it while preserving their original keys.
Define outcomes and review ownership
Agree match, non-match, related and unresolved states. Set which contradictions block automation and which team adjudicates exceptions.
Build the difficult truth set
Sample across countries, scripts, data sources and completeness levels. Include group structures, historical names, branches and common-name collisions.
Pilot one bounded workflow
Start with a clear population such as new supplier onboarding or CRM enrichment. Measure false matches, missed matches, review effort and downstream corrections.
Add event-driven re-resolution
Monitor the company facts that can invalidate a link. Reprocess affected records, compare the new decision with the previous one and route material changes.
Entity resolution should reduce ambiguity without hiding it. The durable asset is not a cleaner company name; it is a governed identity graph that connects every business record to the legal entity, relationship and evidence behind the decision.
Entity resolution software questions answered
What is entity resolution software?
Entity resolution software identifies records that refer to the same real-world entity, links them to a stable identity and separates genuine duplicates from related or different entities.
What is entity resolution for companies?
It is the process of matching business records to the correct legal company using scoped identifiers, names, addresses, domains, registry evidence and corporate relationships.
How is entity resolution different from deduplication?
Deduplication removes repeated records, usually within one dataset. Entity resolution can link incomplete records across systems and explicitly represent related companies that must remain separate.
Is entity resolution the same as master data management?
No. Entity resolution is a matching and linking capability. Master data management is a broader discipline for governing, distributing and maintaining authoritative data, which may use entity resolution.
Can a company name uniquely identify a business?
Usually not. Names can change, be translated, omit legal suffixes or be shared by unrelated companies. Use the name with jurisdiction, identifiers and other evidence.
What is the strongest company matching field?
A valid official registration number combined with its jurisdiction or issuing registry is often the strongest key. Its scope and source must still be validated.
Should parent companies and subsidiaries be merged?
No. They are distinct legal entities. Resolve each one separately, then connect them with a defined corporate relationship.
How should uncertain matches be handled?
Return a possible-match or unresolved outcome with candidates, agreement reasons, conflicts and source evidence, then route material cases to an authorised reviewer.
How is entity resolution accuracy measured?
Use precision, recall and false-positive and false-negative analysis on an adjudicated truth set. Break results down by country, source and data completeness, and also measure review effort.
When should company records be re-resolved?
Re-resolve when relevant names, identifiers, addresses, legal status, corporate relationships or source records change, and when a material ruleset or model update is released.
Connect every record to the right company.
Resolve legal entities with registry identifiers, relationship context and source-backed evidence.